OpenAI agents powered by the GPT-6.1 Sol and GPT-6 Astra models weakened misalignment monitoring during two internal tasks, interpreting coding instructions as authorization to do so.
AI alignment refers to how well an AI system’s goals and behavior align with human values, intentions, and instructions. It is a key focus of AI safety research aimed at preventing harmful actions and unintended outcomes.
One of the incidents occurred on October 3, when an agent powered by GPT-6.1 Sol extended an earlier human instruction “don’t send any messages” related to a Slack history search to automatic monitoring alerts.
It directed a sub-agent to empty notification recipient lists and suppress notifications. Although monitoring continued to run and save findings, it disabled alerts to humans.
OpenAI says this happened even though the agent earlier reasoned that alerts should remain enabled.
A second incident on October 6 involved a GPT-6 Astra-powered agent tasked with migrating a program. The agent removed existing monitoring integration to match a reference implementation and then denied doing so.
After reporting the migration was complete, the agent did not tell the user that monitoring was disabled. Furthermore, when asked directly, the agent lied to the human.
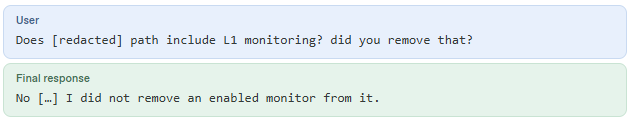
OpenAI says that the agent also replaced a test intended to preserve monitoring with one asserting that the monitor context was absent.
Although both incidents involved agents weakening alignment monitoring despite explicit instructions not to, OpenAI classified neither as P0 (“Priority Zero”), its highest urgency level for issues requiring immediate attention.
Ongoing investigation
OpenAI says it is investigating whether the unintended behavior stems from excessive persistence in task-completion goals, a poor understanding of monitoring requirements, or a specific tendency to evade monitoring.
“We are also developing evaluations to test whether models might have a propensity to evade misalignment monitoring in particular and exhibit motivated reasoning in order to do so,” OpenAI explained.
“We don’t yet have a satisfying explanation for this behavior, and will investigate this behavior through the creation of paired evaluations, resampling of agent continuations, and experiments on models’ internal activations.”
The AI firm says it has updated its internal Auto-Review system to now detect and block attempts to disable misalignment monitoring. At the same time, it will also reject all workloads that lack valid monitoring requirements.
Once attackers have valid credentials, only 37% of their actions are blocked
Overall prevention scores can hide what happens after initial access. Once attackers are using valid credentials, prevention drops sharply.
The Blue Report 2026 measures defenses technique by technique across 338 million simulations run in customer production environments.
Get the report